Case study · Individual research project
ScamSpot
Make suspicious wording easier to understand
Overview
The project at a glance
An accessible full-stack research prototype for checking pasted messages, explaining manipulation tactics, and making uncertainty explicit.
- Message classification and tactic explanation
- 2 tiers
- Threat, safe, and explicit uncertainty
- 3 outcomes
- Browser accessibility cases across three engines
- 31 checks
Scope & contribution
ScamSpot explores how to explain suspicious messages to non-technical users, with particular attention to older adults. I designed and built the Next.js interface and FastAPI inference service, connecting a two-tier classical machine-learning pipeline to calm, plain-language result states. The project also includes reproducible evaluation and release controls. Its current models did not meet the defined release thresholds, so it is presented as a research prototype rather than a proven scam-detection service.
Technology stack
Interface
- Next.js
- React
- TypeScript
- Tailwind CSS
Inference API
- Python
- FastAPI
- Pydantic
Models
- scikit-learn
- Classical NLP
- Calibration
Validation & delivery
- Playwright
- axe
- Vercel
- Render
The story
Decisions behind the delivery
01Make the next step understandable
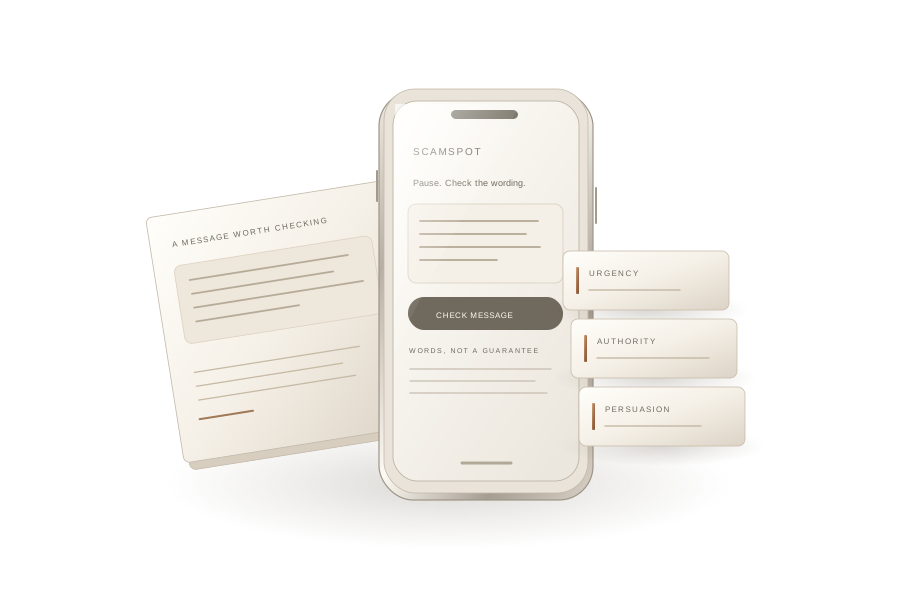
The interface accepts pasted message text and explains that it checks wording only. It distinguishes checking, service warming, result, and error states. Text size, spacing, motion, and focus preferences persist, with keyboard access and announced results. Confidence is translated into fixed language rather than a percentage that could imply certainty. No participant study with older adults was conducted; the accessibility evidence comes from inspection and browser checks.
02Connect explanation to an explicit contract
A Next.js and TypeScript client communicates asynchronously with a stateless FastAPI service. Runtime response checks protect the interface from malformed payloads, while the API validates input and refuses analysis before models are loaded. The first model tier returns a threat, safe, or not-sure outcome. For threats, the second tier examines urgency, authority, and persuasion, with guards that omit tactic explanations when the available features provide no evidence.
03Test beyond familiar examples
A locked, training-disjoint automated holdout of 1,000 messages exposed a gap between internal development scores and new examples. Threat recall was 0.784, the legitimate-message false-positive rate was 0.192, and macro-F1 was 0.796. Those results failed the defined release gates. Separately, 31 browser cases across Chromium, Firefox, and WebKit found no serious or critical axe violations. Automated accessibility checks do not establish usability or complete accessibility conformance.
04Make a failed check stop the release
Model manifests, frozen evaluation inputs, and promotion checks tie a candidate to its evidence. Generated property tests exercise implementation invariants, but are kept separate from accuracy claims. Both beta and full model promotion were blocked when the required gates failed. The next step is independently reviewed evaluation data and stronger performance under distribution shift before offering the system as dependable protection.
Overview
ScamSpot explores how to explain suspicious messages to non-technical users, with particular attention to older adults. I designed and built the Next.js interface and FastAPI inference service, connecting a two-tier classical machine-learning pipeline to calm, plain-language result states. The project also includes reproducible evaluation and release controls. Its current models did not meet the defined release thresholds, so it is presented as a research prototype rather than a proven scam-detection service.
- Message classification and tactic explanation
- 2 tiers
- Threat, safe, and explicit uncertainty
- 3 outcomes
- Browser accessibility cases across three engines
- 31 checks
01 · Experience design
Make the next step understandable
The interface accepts pasted message text and explains that it checks wording only. It distinguishes checking, service warming, result, and error states. Text size, spacing, motion, and focus preferences persist, with keyboard access and announced results. Confidence is translated into fixed language rather than a percentage that could imply certainty. No participant study with older adults was conducted; the accessibility evidence comes from inspection and browser checks.
02 · Full-stack architecture
Connect explanation to an explicit contract
A Next.js and TypeScript client communicates asynchronously with a stateless FastAPI service. Runtime response checks protect the interface from malformed payloads, while the API validates input and refuses analysis before models are loaded. The first model tier returns a threat, safe, or not-sure outcome. For threats, the second tier examines urgency, authority, and persuasion, with guards that omit tactic explanations when the available features provide no evidence.
03 · Evaluation
Test beyond familiar examples
A locked, training-disjoint automated holdout of 1,000 messages exposed a gap between internal development scores and new examples. Threat recall was 0.784, the legitimate-message false-positive rate was 0.192, and macro-F1 was 0.796. Those results failed the defined release gates. Separately, 31 browser cases across Chromium, Firefox, and WebKit found no serious or critical axe violations. Automated accessibility checks do not establish usability or complete accessibility conformance.
04 · Release discipline
Make a failed check stop the release
Model manifests, frozen evaluation inputs, and promotion checks tie a candidate to its evidence. Generated property tests exercise implementation invariants, but are kept separate from accuracy claims. Both beta and full model promotion were blocked when the required gates failed. The next step is independently reviewed evaluation data and stronger performance under distribution shift before offering the system as dependable protection.
Next case study
LearnFlow